


The bottleneck isn’t compute. It’s how we configure it.
Your HPC already has an optimizer. It’s a config file somebody wrote once. The gap between that file and the most efficient way to run your workload is the configuration tax, and you pay it on every run in slower results and higher compute bills.

Every process needs something different
Within a single pipeline, some steps are compute-bound and others are memory- or I/O-bound. One static configuration overprovisions some steps and starves the rest.

Too many options to test manually
Hundreds of instance types, storage options, and parallelism settings, with Spot prices and capacity that shift by the hour. No team can test them all for every workload.

Optimal doesn’t stay optimal
New GPUs, CPUs, and features ship constantly. A configuration tuned last quarter quietly falls behind unless someone benchmarks it again.
How it works
Measured, not guessed. Every strategy decision comes from Benchmark Intelligence: measured performance data from your own workloads.
01 Benchmark
Submit your workloads and pipelines from the web UI, CLI, Nextflow, or AI agents via MCP. Fovus profiles each process automatically to find what limits it, whether that’s compute, memory, or I/O, and how well it scales with more cores. Generic defaults can’t tell you that. Benchmarking is built in, at no extra charge.
02 Optimize and run
Your benchmark data maps each process’s options, from hardware and parallelism to storage and pricing, by runtime and cost.
The AI engine picks the most efficient strategy for each process, down to the GPU type, against live AWS pricing and availability, weighted by your time and cost priority.
License-bound workloads scale with license availability, so the licenses you pay for stay in use.
License-free workloads fan out as parallel tasks across AWS regions and zones, for over 100x faster time-to-insight.
Spot capacity runs with memory checkpointing, so interrupted jobs resume where they left off instead of starting over.
03 Continuously improve
As AWS ships new hardware, Fovus re-benchmarks your workloads and upgrades your strategies automatically, with no change to your workflow.


1/5

1/5
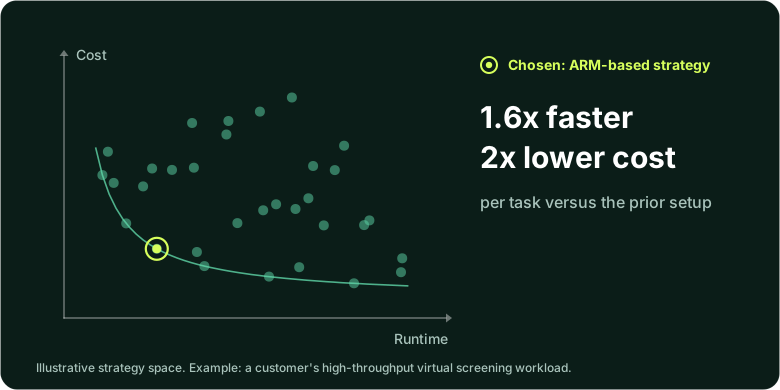
At first benchmark
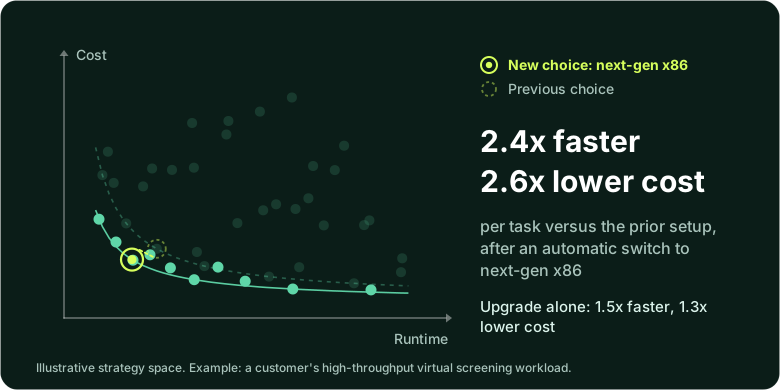
Six months later
Everything between your workload and AWS, handled.
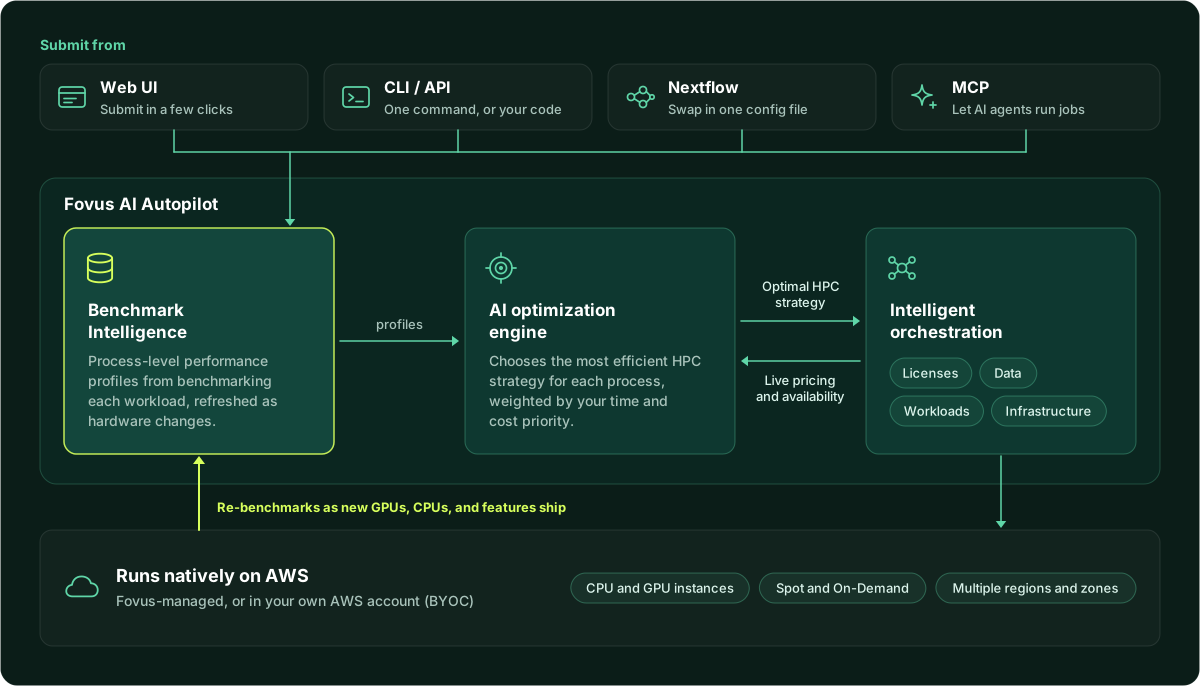
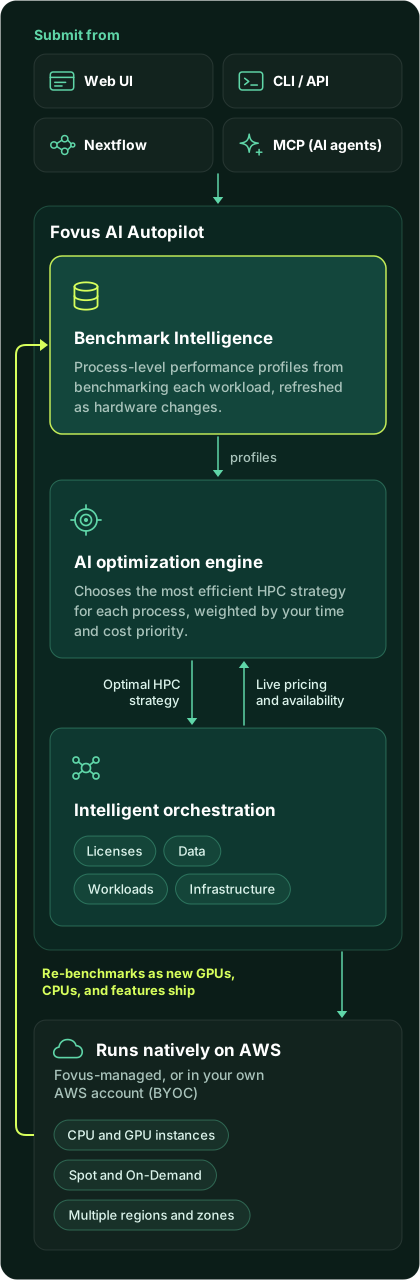
Submit from the web UI, CLI and API, Nextflow, or AI agents via MCP. The Fovus AI optimization engine pairs Benchmark Intelligence with live AWS pricing and availability to choose each strategy, then orchestrates the licenses, data, workloads, and infrastructure behind the run.
It’s serverless and runs natively on AWS, managed by Fovus or inside your own AWS account (BYOC).
Why teams run production HPC on Fovus

Zero-touch
Submit from the web UI, CLI, Nextflow, or MCP. No instance types, AMIs, VPCs, or schedulers to set up per job. Focus on innovation, not infrastructure.

Provably Optimal
Benchmark Intelligence chooses each strategy from your own workloads’ measured performance and cost, so every decision is backed by data, not defaults.

Always Current
When AWS ships new hardware, Fovus re-benchmarks and upgrades your strategies, so your runs keep pace with the cloud.
BYOC. Run Fovus inside your own AWS account, under your security controls, guardrails, and AWS pricing agreements, with no data leaving your account. Or let Fovus manage it for you. Compare deployment options

Proven on production workloads
Life sciences and engineering teams run production HPC on Fovus. Here’s what changed for them.

Manufacturing
“Fovus empowered us to easily migrate 100% of our HPC workloads to the cloud. Fovus intelligently optimizes our HPC strategies and maximizes our license utilization, improving our digital innovation productivity by +30%.”


The results


1
day / week
Time back for innovation
Before Fovus, customer teams lost 10 to 30% of their innovation time to infrastructure work, roughly a day a week. That time now goes to science and engineering.


100
x+
Time-to-insight
Over 100x faster time-to-insight by scaling each process across AWS regions and zones. Chemspace cut compound screening from 4 weeks to 6 hours.

70
%+
Compute cost
Lower compute costs than static configurations, from benchmark-driven strategies and intelligent use of Spot capacity.
We publish our numbers
Benchmarks on real pipelines and simulations, including results co-published with AWS.
About $0.70 per sample
nf-core/rnaseq on AWS Spot capacity, CPU only, from a benchmark co-published with AWS on the AWS Partner Network blog.
From $0.95 per 10,000 ligands
Large-scale molecular docking with Vina GPU on Fovus.
3x faster at 4x lower cost
Multibody dynamics design of experiments (DOE) runs at Komatsu, compared with their prior solution.
Browse by workload: Vina GPU docking, AlphaFold 3, nf-core/rnaseq and sarek, and GROMACS and OpenMM.
Who it’s for
Everyone who touches HPC pays the configuration tax differently. Here’s what changes for each team.
Platform and IT leaders
Today: Cloud HPC spend that’s hard to defend, license contention, and a platform your team has to build and keep tuned.
With Fovus: Run engineering and research HPC in your own AWS account. Your team sets the guardrails for regions, spend, and priority; Benchmark Intelligence makes every configuration decision inside them. All of it is scriptable from CI.
Proof: Komatsu moved 100% of its production CAE workloads to the cloud, with nearly full license utilization when jobs are running.
Computational scientists
Today: Queues, compute caps, and GPUs that aren’t there when a screening campaign starts.
With Fovus: Run screening, simulation, and structure prediction at full scale without learning the cloud. Submit from the web UI or CLI; Fovus picks the hardware, scales out, and recovers from interruptions. Same budget, more shots on goal.
Proof: A biotech startup ran five design-make-test-analyze cycles in 6 days instead of 24.
Bioinformatics leaders
Today: Cost per sample that climbs with volume, and pipeline runs lost to Spot interruptions.
With Fovus: Lower cost per sample on the Nextflow pipelines you already run. Swap in one config file, and runs recover from interruptions on their own. Every dollar saved drops to margin.
Proof: nf-core/rnaseq at about $0.70 per sample on Spot, in a benchmark co-published with AWS.
Simulation engineers
Today: Long solver runs, license queues, and clusters tuned by hand.
With Fovus: Run CFD, structural analysis, and multibody dynamics, including multi-node MPI and license-bound tools like Ansys Mechanical, on hardware benchmarked for each job, with licenses queued and balanced automatically.
Proof: Komatsu cut structural analysis runtime by 4.5x.
